

sqlmc_script_complete: Result
Three of those carry design intent an agent author should not have to infer.
| Field | |
|---|---|
ok |
Whether the call produced an answer. An empty list is an answer |
errors[] |
{ code, name, path } — codes, never prose |
replacementStart |
Where an accepted item starts overwriting |
replacementLength |
How much it overwrites |
totalItems |
How many the engine offered, before maxItems capped it |
items[] |
{ label, insertText, kind, detail, drift }, best first |
schemaReadUtc |
When the reference target's schema was read, or null when none has been |
Three of those carry design intent an agent author should not have to infer.
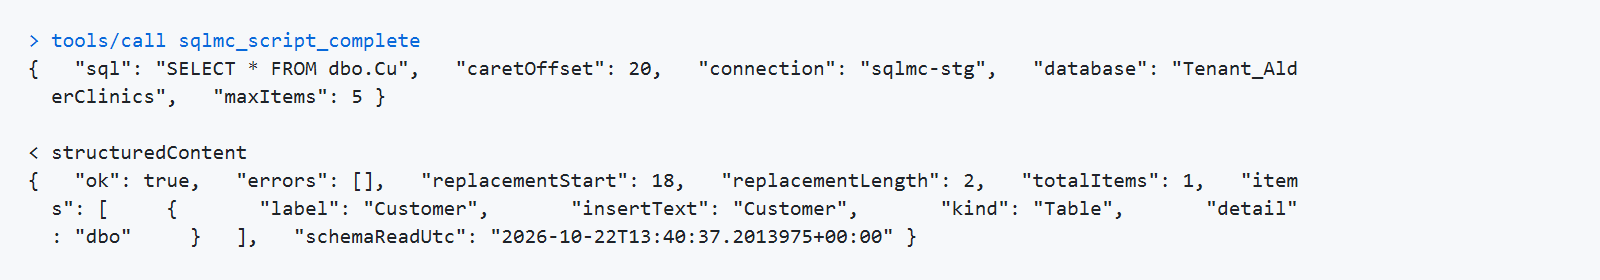
The replacement span travels with the items. Write an accepted item back using
replacementStart and replacementLength rather than working out where the word started. That
calculation disagrees with the analyzer's on exactly the awkward cases — a temp table's #, a local
variable's @, a bracketed name — and there a wrong span eats text the caller did not mean to
touch.
totalItems is separate from items.length. A truncated answer says so rather than reading as
the whole of it. If they differ and you needed the whole set, raise maxItems and ask again.
schemaReadUtc is the age of the answer. An agent deciding whether to trust a column list wants
that, not just the list. Null means no schema has been read for this target, so every item is a
keyword, a snippet or a variable.